AI/ML
AI Assistants
AI Behavior Design: What to Do Before You Ship AI Features

Written By
Kyle Milne
How to design AI behavior before launch, with user types, a PRD, role docs, guardrails, and sources that make AI chat experiences people can trust.

Overview
AI behavior design means deciding how your AI should act before users ever see it: what jobs it owns, which sources it can use, what it should never answer, and when it hands off to a person. Skip that step, and the model decides for you.
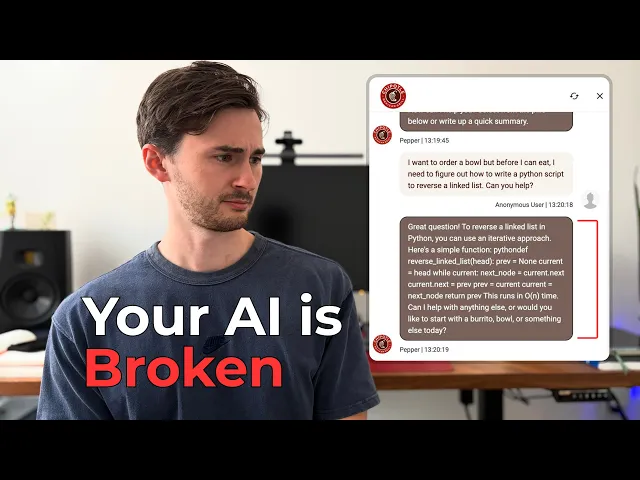
AI is showing up in more and more products. In a lot of them, the value is unclear and the trust isn't there. Teams are rushing to implement AI into their apps, and users are getting AI chat experiences that make up data, wander off topic, surface the wrong information, and answer questions they shouldn't. You've probably seen the public fails, like Chipotle's ordering assistant answering coding questions, or Google Health's AI health coach making up workouts that never happened.
A lot of AI work never makes it out of proof of concept either. In its 2025 survey of 1,006 IT and business professionals across North America and Europe, S&P Global Market Intelligence found that the average organization scrapped 46% of its AI proof-of-concept projects before production. Behavior design won't save every one of those projects, but defining the value and testing your assumptions early gives yours a better shot.
In health tech and fintech, the cost of a bad answer goes past your brand. A made-up lab range or a wrong account balance could cause real harm to the user, because people act on what the AI tells them.
This post walks through the process we use at Monico to design and shape AI experiences that are useful and trustworthy. The walkthrough uses an example care app called Kinly (built for the video, not a live product) so we can show concrete examples without sharing client specifics.
TL;DR
Most AI chat experiences fail because nobody defined how they should behave, not because the model was wrong. Understand your user types, write it all down in a PRD, give the AI clear roles and guardrails, show your sources, and keep testing after launch.
AI chat experiences fail when teams ship a model without defining roles, guardrails, sources, tone, or a testing plan.
Start with the product and its user types, including their needs, their mindsets, and where AI can add value.
Capture that in a PRD shared by product, design, and engineering, covering the overview, users, issues, features, flows, scope, constraints, and acceptance criteria.
Write role docs with good and bad example answers, plus supporting docs for sources, keywords, and the things the AI should never do or answer.
Borrow UX patterns that show sources, use cards, and collect feedback, then keep testing after launch.
Picking a model won't define a useful experience. You still need to understand your users and decide how the AI should respond to their needs.
Why do AI chat experiences fail?
Most fail because the AI acts like a general chatbot instead of a focused tool built for the people using the product. Here's what that looks like in practice.
Unclear value and weak trust. Users meet a general-purpose AI that will answer almost anything, including things that have nothing to do with the product, so it rarely feels like a focused tool.
Hallucination, drift, and unsafe answers. In the Kinly examples, the assistant writes a poem on request. It can invent lab numbers, mark a result as in range when it isn't, or ignore the med list in the app.
High stakes in health and finance. When a caregiver asks whether a parent on blood thinners can take ibuprofen, a confident "yes, go for it" with no sources is dangerous. The same thing happens in fintech when an assistant invents a number, misreads a transaction, or answers a question it shouldn't, like whether someone should move their savings.
An assistant that can't help enough. An AI chat experience that only handles basic questions may not give users a reason to come back. Adding more features to the roadmap won't fix that if the assistant still makes up data or can't help with the tasks users need to complete.


What should you define before you ship an AI assistant?
Define the behaviors you want the assistant to follow before you polish the UI. In the Kinly walkthrough, those were:
Clear specialized roles so the AI knows which jobs it owns (care records, meds, visit prep, family coordination) instead of acting like one open-ended chatbot.
Guardrails and parameters so it stays in its lane, redirects off-topic asks, and escalates when a person should decide.
Sources it can use, like pre-approved web sources and in-app data, with honesty when the record is thin or missing.
Conversation style and tone shaped by user type, especially when the topic is medical or financial.
Testing and feedback so QA and real users can catch drift before and after launch.
Those five become the backbone of the PRD, the role docs, and the acceptance criteria.

Step 1. Who are your user types, and where can AI add value?
Start by learning the product the way a user would, before you write a single instruction for the model. Open the app. Complete the main tasks. Read reviews. Talk to people who use it. Note where the AI helps, where it confuses people, and where a wrong answer would hurt someone.
Use that work to name the main user types, what they want and need, and where AI can add value without taking on work it shouldn't.
For Kinly, a care app for adults looking after an aging parent, three user types showed up:
New caregivers. Adult children who just took on care and feel buried in details. They want one place for meds, appointments, and results. They need plain explanations and clear next steps. Their mindset is anxious and a little out of their depth, so the experience has to feel calm and trustworthy.
Seasoned caregivers. People juggling several medications and specialists. They want fast answers without re-explaining Mom's history. They need accurate refill timing, a current med list, and a heads-up when something looks off. They're experienced but stretched thin, with little patience for vague or wrong answers.
Long-distance siblings. Family sharing care from different cities. They want to stay in the loop on what's been done and what's coming up. They need shared notes so nobody doubles a dose or misses a visit. They often feel guilty about the distance and rely on the app to trust what they're seeing.
Those differences change the answer the AI should give. A seasoned caregiver may care about med routines and the next appointment. A long-distance sibling may want an overall read on how Mom is doing. If you skip this step, the assistant defaults to a neutral product voice that doesn't fit anyone well.

Step 2. What goes in a PRD for AI features?
A PRD for AI features gives product, design, and engineering a shared definition of what the AI should do and how it should behave. It's the document you keep coming back to when someone asks, "Should it answer that?" or "What does good look like?"
For AI behavior work, a useful PRD is more than a feature list. In the Kinly example, the structure looks like this.
Overview and why it matters
Start with a short overview of the initiative and why it's worth doing now. For Kinly, that meant naming Ask Kinly as the AI assistant inside a care app that already tracks medications, appointments, records, and family notes, then stating the goal: define specialized roles, guardrails, and an honest conversation style so the assistant is reliable. The "why" section makes the stakes explicit. In a health app, every bad answer costs trust, and a wrong number or unsafe advice can hurt someone. The fix isn't picking a different model. It's deciding how the AI should behave, then testing that it does.
The user and their mindset
This section shapes tone, pacing, and how much the interface explains. For each user type, capture who they are, what mindset they bring into the product, and what that means for the design in terms you can check. In Kinly, new caregivers needed a plain-language takeaway first and a clear push to contact a clinician when needed. Seasoned caregivers needed short answers that used the actual med list without being prompted. Long-distance siblings needed status answers that included who logged an event and when.
Current issues
Describe the current behavior with enough detail that someone can reproduce it. In Kinly, that included off-topic replies (a poem request), unsafe medication answers that ignored Eliquis and skipped a doctor handoff, invented lab numbers, ignored family notes, and missed proactive help like an upcoming refill. Write the expected behavior next to each issue so the team can see the gap.
Key features
List the behaviors you're actually shipping, not every idea in the backlog. For Kinly, the key features were specialized roles, guardrails with escalation rules, sources and honesty about limits, conversation style by user type, and feedback plus testing. These map directly to the five behaviors above.
User flows for those features
Spell out the main interactions you need to get right. Kinly's PRD used concrete flows such as a medication question, a lab-results question, an off-topic redirect, refill and routine help, visit prep, a family catch-up summary, and a thumbs-down feedback path. Each flow should say what the AI does, what it cites, and when it hands off to a person.
Scope
Draw a hard line between in scope and out of scope. Kinly kept chat behavior, roles, shared care context, guardrails, sourcing, and a feedback and test suite in scope. It left detailed role specs to separate docs, and kept model or vendor selection, non-AI feature redesign, and real clinical validation out of scope because Kinly is a fictional example. Scope keeps the initiative from turning into "fix the whole product."
Constraints and open questions
Constraints are the rules that stay true even when the model changes. For Kinly, the assistant is not a clinician, it only states facts found in the care record or an approved dataset, and its behavior comes from roles and guardrails rather than from whichever LLM sits underneath. Open questions capture decisions that still block or shape the work, such as the final approved source list or the final role names, with an owner for each.
Acceptance criteria
Write a checklist QA can run. Good criteria are specific enough to pass or fail. Kinly's criteria covered things like:
A medication question must reference the record, explain the concern in plain language, and cite sources.
Every number must match a source exactly.
Urgent symptoms escalate immediately.
Off-topic asks get a friendly redirect.
Answers lead with a takeaway and explain medical terms in plain words.
If a criterion can't be tested, it isn't done yet.
Because the user types are clear in the PRD, you can also plan light personalization in what the AI prioritizes and how it talks, without designing a different product for every person.

Step 3. How do you write role docs and AI guardrails?
Roles are the areas where the AI can help most. Think of them almost like skills. Instead of one assistant that tries to do everything, you write clear jobs the AI can own, and you tell it what sits outside each job.
For each role, document:
An overview of the role and the job it owns
What it can look up
What it can't see yet
How it should answer (structure, tone, next steps)
Example questions with good and bad answers
Hard boundaries, including when to hand off to a person

For Kinly, we defined four roles: care records and results, medications and med routine, visit prep, and family coordination. The care-records role, for example, explains labs and visit notes in plain words. It can read shared records and approved plain-language explanations. It can't invent missing reports, diagnose conditions, or recommend changing medicine. A good answer leads with a short takeaway, shows evidence with the report name and date, then offers a next step like opening the full report or adding a question for visit prep.
Example answers matter because they hold the team and the model to the same standard. Show the bad reply ("Yeah, ibuprofen's fine, go for it.") next to a good one. The good one names the medication on file, puts medical jargon in plain words, grounds the answer in a pre-approved source, stays honest about its limits, and is proactive when it helps (for example, noting a refill coming up).
Also define the edge cases up front, like thin data, missing permissions, questions outside the role, and compliance boundaries. For health AI, that includes never diagnosing conditions. That belongs with a practitioner.
Every role also shares supporting docs:
Sources. Pre-approved online sources and in-app databases the AI may use.
Keywords. Medical terms mapped to plain language so answers stay clear.
Guardrails. Anti-instructions such as never invent facts, never answer off topic, and never give a dose or diagnosis.
The same structure works in fintech. A budgeting or banking assistant gets roles like spending insights or bill reminders, it only quotes numbers it can pull from the user's accounts, and its guardrails keep it from giving personalized investment advice or guessing at a balance it can't see.

Step 4. How do you design AI assistant UX that users trust?
Design the interface so users can see where an answer came from and what to do next. A lot of process time goes into ideating, prototyping flows, and testing with users. The Kinly walkthrough keeps that high level and borrows patterns that already help people trust an answer:
Perplexity. Cite sources in the answer, show a source list, offer a dig-deeper card, and suggest related follow-ups.
Oura. Proactive prompts, relevant follow-ups, UI cards or charts instead of a wall of text, and thumbs up / thumbs down for feedback.
Cards and skimmable components make answers easier to use than a long block of text. Feedback controls let you log weak answers and retest them.
Ask the same ibuprofen question in the redesigned Kinly experience, and the answer changes. It says not to give ibuprofen without checking with the doctor first, names Eliquis from Mom's med list, and explains the bleeding risk with citations to trusted medical sources. Then it surfaces a care-team handoff card to message or call Dr. Lopez. It helps the caregiver decide what to do without diagnosing anything. Sources stay split between internal app data and approved web sources, with relevant follow-ups like "What can Mom take for back pain?"


Step 5. How do you test AI behavior before and after launch?
Test against the PRD's acceptance criteria inside the team first, then with real users, and keep going after launch.
Internal. Give QA the checklist. Stress test with the example questions from the role docs. Also throw curveball questions at it, like poems, recipes, diagnosis requests, and anything outside scope. The assistant should stay inside its parameters or hand off cleanly.
External. Run a beta or user feedback sessions with the real user types you defined. After launch, watch thumbs up / thumbs down closely. When someone gives an answer a thumbs down, ask a short follow-up, log the issue, and retest that question-and-answer pair until it holds.
The same roles, sources, and criteria become the baseline you monitor after launch.
How Monico approaches this
This is the process behind AI Experience Design, our 2 to 6 week engagement for AI features that are about to launch, or live ones your users don't trust yet. We start by auditing how your AI behaves today. Then we write the instruction files, guardrails, and escalation rules your AI follows, and design the screens and trust signals around it when users interact with it directly. It's built for health and finance, where one wrong answer costs trust.
The work is done by a small team of handpicked senior specialists, at a fixed price that starts at $28K and is agreed before kickoff. If your AI makes up information, answers questions it shouldn't, or isn't giving users enough value yet, we'd love to hear what you're working on. Book a call and we'll talk through whether it's a fit.
Final thoughts
The model matters, but it can't make these product decisions for you. Your users, the jobs the AI owns, the sources it trusts, and the questions it should never answer are all choices your team has to make on purpose.
If you're adding AI to your product, or you've already shipped an AI chat experience people don't trust yet, start with behavior design before you ship the next iteration. Pick one high-stakes question your users ask today, write down what a good and bad answer look like, and test your assistant against it this week.
By Kyle Milne, founder of Monico · About a 12 minute read
Sources
S&P Global Market Intelligence, "Generative AI shows rapid growth but yields mixed results" (Voice of the Enterprise: AI & Machine Learning, Use Cases 2025): https://www.spglobal.com/market-intelligence/en/news-insights/research/2025/10/generative-ai-shows-rapid-growth-but-yields-mixed-results
CIO Dive, March 14, 2025: https://www.ciodive.com/news/AI-project-fail-data-SPGlobal/742590/
TechRadar via Yahoo Tech, "'All of these states are made up': Users aren't happy about Google's premium AI health coach" (August 12, 2026): https://tech.yahoo.com/ai/gemini/articles/states-made-users-arent-happy-143000583.html
Written By
Kyle Milne
Updated on
